
How to Monitor and Evaluate AI Agents in Production
Learn how to monitor and evaluate AI agents in production using logs, traces, metrics, and task-specific evaluations. This guide explains how to reconstruct agent runs, distinguish technical completion from task success, locate root causes, and turn production evidence into continuous improvement.
An AI agent can complete a request without throwing an error and still fail at its job. It may choose the wrong tool, retrieve weak evidence, take an unnecessary path, or return an answer that does not meet the business requirement. The run succeeded technically; the task failed operationally.
This is why AI agent monitoring must extend beyond uptime, latency, and error rates. Teams need enough production evidence to reconstruct what happened, evaluate whether the result was acceptable, and decide where a correction should be made.
NIST’s 2026 report on deployed AI systems explains why pre-release testing is not enough: real environments introduce changing inputs, nondeterministic outputs, and consequences that controlled evaluations cannot fully anticipate.
Monitoring shows what changed. Observability helps explain why. Evaluation determines whether the result was good enough.
Together, these practices provide the operational evidence enterprises need as agents move from isolated pilots into everyday business processes. At portfolio scale, that evidence becomes part of a broader AI agent management platform.
Monitoring, Observability, and Evaluation
These practices overlap, but they answer different questions.
| Practice | Primary question | Typical evidence |
| Monitoring | What changed over time? | Volume, failures, latency, feedback, token use, cost |
| Observability | Why did this run behave this way? | Traces, model and tool calls, context, workflow path |
| Evaluation | Was the result good enough? | Task success, grounding, policy checks, human review |
Monitoring without evaluation can show that an agent is fast and inexpensive without showing whether it is useful. Evaluation without observability can identify a poor result without revealing the cause. Observability without monitoring can produce detailed traces that nobody reviews until a user reports a failure.
When an issue appears, teams should inspect the relevant run, assess the outcome, and use the evidence to decide what needs to change.
This becomes more difficult as organizations encounter AI agent sprawl. When agents, owners, logs, and costs are distributed across teams, good telemetry may still fail to produce an enterprise-level view.
Start With One Reconstructable Run
Before selecting dashboards or AI agent metrics, define what the team must know when one production result is questioned.
A useful run record connects the request to the agent and release, trigger source, workflow, user or system context, model and knowledge operations, tool calls, approvals, timing, usage, and final outcome. The objective is not to capture private chain-of-thought. It is to retain inspectable inputs, outputs, actions, dependencies, and workflow decisions.
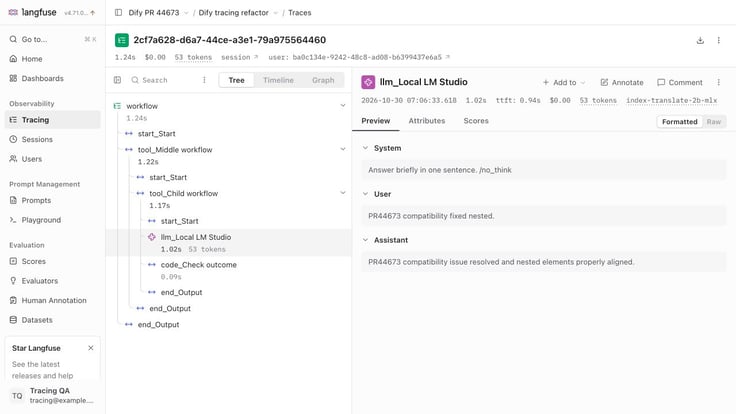
External observability tools can make this execution record easier to inspect by presenting model calls, tool activity, timing, token usage, and outputs as a trace.
More data is not automatically better. Prompts, retrieved documents, tool parameters, and user messages may contain confidential information. OpenTelemetry’s guidance for generative AI telemetry therefore treats collection, redaction, access, sampling, and retention as part of monitoring design.
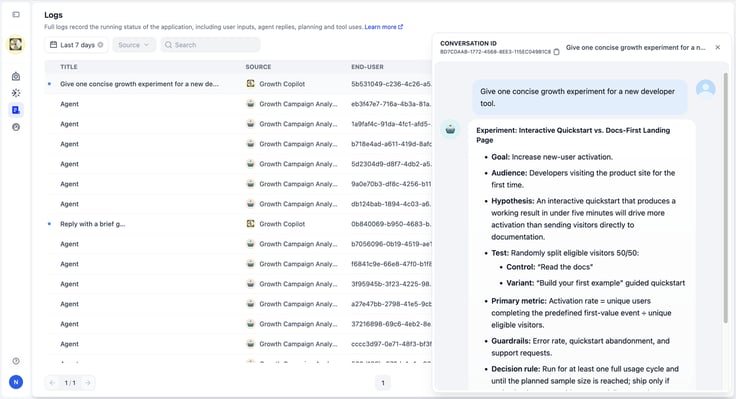
In Dify, Logs help teams locate conversations and Workflow runs, review source context and feedback, and inspect execution details. The current Logs documentation should be used to verify coverage for each app and execution context.
Monitor at Three Levels
At the run level, teams should be able to identify the task, source, model, knowledge, tools, approvals, timing, and result. A successful status does not prove task success.
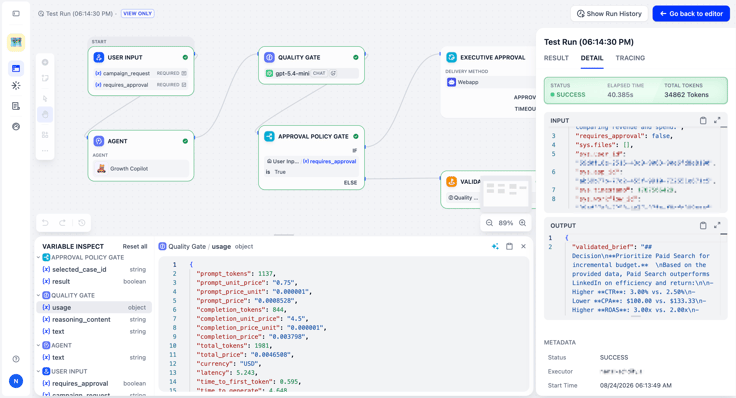
At the workflow level, tracing should expose the relevant path, inputs, outputs, timing, and failure state. The root cause may sit outside the agent: an upstream node may pass incomplete data, a branch may route
incorrectly, or a validator may accept an output it should reject.
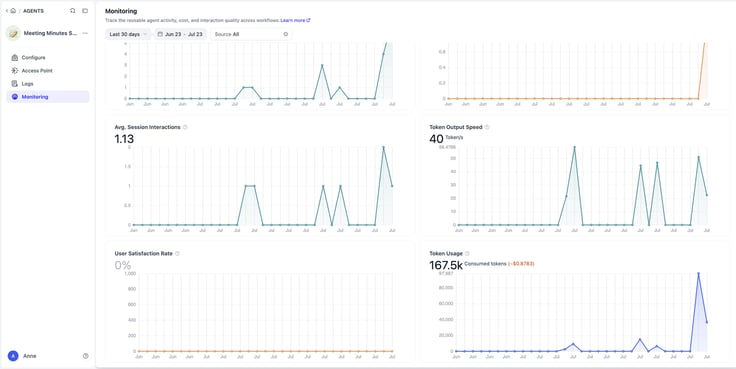
At the agent and portfolio level, trend monitoring should compare volume, task completion, latency, dependency failures, feedback, evaluation results, token usage, and cost across agents, sources, workflows, models, releases, or task types.
Choose Metrics That Lead to Decisions
The goal is not to maximize the number of charts. Each metric should inform a decision.
| Metric group | Examples | Decision it supports |
| Reliability | Success, timeout, tool failure, retries | Is the execution path dependable? |
| Performance | End-to-end latency, node time | Where is the user waiting? |
| Quality | Completion, grounding, relevance, rule adherence | Does the result meet the task standard? |
| Behavior and safety | Denied actions, unusual tool use, approval changes | Is the agent inside its intended boundary? |
| Cost | Tokens, model spend, tool charges | Where is cost changing, and why? |
| Business outcome | Resolution, acceptance, cycle time | Is the agent creating useful results? |
Technical completion and task success must remain separate. A single overall quality score can also hide where the fix belongs: poor grounding points toward retrieval or source data, while incorrect tool use points toward routing or tool configuration.
OWASP’s guidance on model monitoring identifies input logs, output logs, and tool-call traces as useful evidence for agentic incident response. Expected behavior should still be defined for the specific agent rather than inferred from a universal baseline.
Cost must be interpreted in context. A more expensive run may be justified if it completes a high-value task reliably, while a cheap run that creates rework destroys value. The separate guide to tracking real AI agent costs and business value covers attribution, unit economics, and portfolio decisions.
Evaluate Outcomes, Not Only Outputs
AI agent evaluation should reflect the task the agent was expected to complete, not only the fluency of its final response.
Outcome evaluation asks whether the task was completed correctly. Trajectory evaluation asks whether the agent used the right tools and followed an acceptable path. Policy evaluation asks whether the run stayed inside required data, action, and approval boundaries. Operational evaluation asks whether the result met acceptable time, cost, reliability, and escalation limits.
Offline evaluation tests proposed changes against representative tasks, difficult cases, historical failures, and high-risk scenarios before release. Online evaluation uses production interactions, sampled reviews, user feedback, automated checks, and downstream outcomes to find behavior the test set did not anticipate.
Automated evaluators can expand coverage, but they should be calibrated against domain experts. Human review remains important when correctness is contextual or the consequences are material. NIST’s evaluation-probe research shows how automated verifiers may test outputs against trusted evidence, but no single evaluator proves correctness for every domain.
Investigate Where the Fix Should Live
When an agent produces a bad result, another prompt instruction is not always the right response.
| Likely layer | Question to investigate |
| Task definition | Did the agent receive a clear goal and constraints? |
| Knowledge | Was the necessary information current and retrieved correctly? |
| Model or routing | Was the selected model suitable for the task? |
| Tool | Did it receive the right parameters and return reliable data? |
| Workflow | Did branching, validation, or approval work as intended? |
| Permissions | Was the action blocked, over-permitted, or executed under the wrong identity? |
| Evaluation | Did the test reflect the business requirement? |
The durable question is not only “How do we fix this answer?” It is “Where should the fix live?” This prevents prompt patches from accumulating around problems caused by data, tools, permissions, or workflow design.
Turn Evidence Into an Improvement Loop
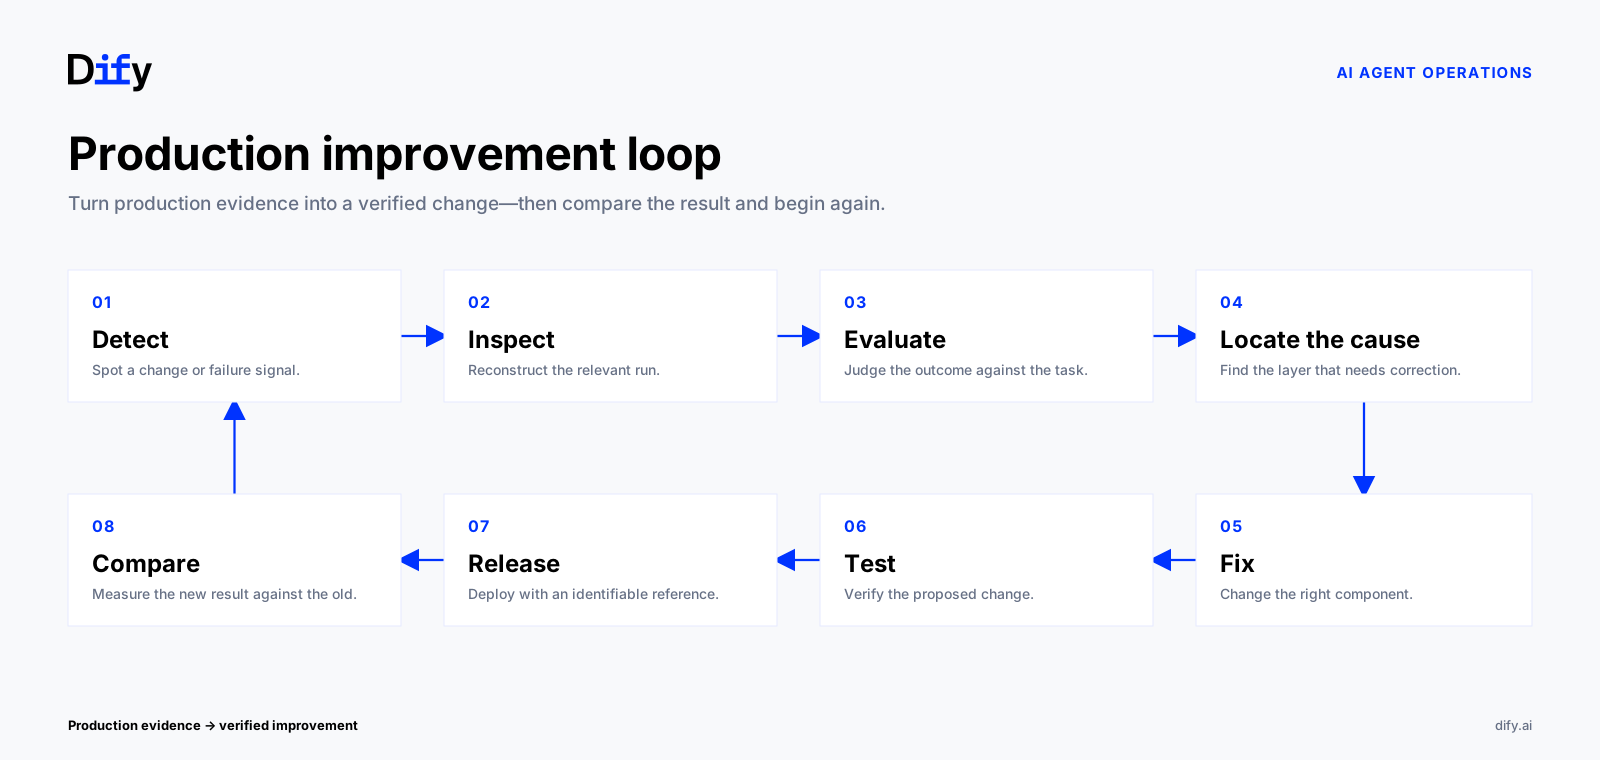
The loop needs an owner and a release reference. Business owners define acceptable outcomes. Technical owners maintain the agent, workflow, and integrations. Domain reviewers provide ground truth where automated scoring is insufficient.
Versioning, reuse, restriction, and retirement belong to AI agent lifecycle management. Monitoring supplies the evidence; lifecycle management determines what should change, continue, scale, or stop. These decisions also help prevent the unmanaged accumulation described in our guide to AI agent sprawl.
Retention should follow risk, privacy, investigation windows, and cost. Longer retention is not automatically safer because logs may contain conversations, retrieved content, tool parameters, and business data.
How Dify Supports Production Monitoring
Dify connects several layers of production evidence with the environment used to build and publish agents and workflows. Logs help locate conversations and runs. Workflow execution details expose supported node paths, inputs, outputs, timing, usage, and failures. Monitoring views show activity and trends, while external observability integrations can extend tracing and evaluation workflows.
Built-in monitoring, run logs, and third-party integrations are different capabilities. Settings and available evidence depend on the app, plan, deployment, and execution context. For current behavior, refer to the official Dashboard and Logs documentation.
When adoption expands faster than centralized oversight, the problem is no longer only debugging. It becomes AI agent management at scale.
Production Monitoring Checklist
Before treating an agent as production-ready, confirm that the team can:
- Identify the agent and release behind any run.
- Reconstruct relevant model, knowledge, tool, and workflow activity.
- Distinguish technical completion from task success.
- Detect changes in reliability, quality, behavior, cost, and business outcomes.
- Reproduce failures while protecting sensitive telemetry.
- Compare evidence before and after a release.
If several of these conditions are missing, the organization may have telemetry without an operating process.
Conclusion
Production monitoring for AI agents is not a larger version of uptime monitoring. An agent can remain available while its evidence weakens, its tool behavior changes, or its output stops meeting the business requirement.
The effective pattern is straightforward: monitor trends, preserve enough evidence to investigate a run, evaluate the result against a task-specific standard, and fix the layer that caused the failure. Then verify the change against new production evidence.
Monitoring tells a team where to look. Evaluation tells it whether intervention is necessary. Ownership turns both into a reliable operating practice.
FAQs
What should teams monitor for an AI agent in production?
Monitor reliability, latency, model and tool activity, task quality, policy exceptions, operating cost, user feedback, and the relevant business outcome.
What is the difference between AI agent monitoring and observability?
Monitoring tracks expected signals over time. Observability provides the execution evidence needed to explain why a specific run behaved as it did.
How is AI agent evaluation different from monitoring?
Monitoring establishes what happened. Evaluation judges whether the outcome met a defined quality, policy, or business standard.
Should teams log every prompt, response, and tool parameter?
Not automatically. Detailed content may improve investigations but can contain confidential information. Capture, redaction, sampling, access, and retention should follow the use case and applicable requirements.
How often should AI agents be evaluated?
Use offline evaluation before meaningful releases and continuous or sampled online evaluation after deployment. Increase coverage as access, impact, inputs, or recent incidents raise risk.
相关文章
- Research
The Guide to AI Agent Management Platforms
Learn what AI agent management platforms do, why enterprises need them, and how to evaluate their governance, monitoring, cost, and lifecycle capabilities.
 Anne Zhu & Zhenan Sun
- Research
Trust Is a Feature: How Dify Is Governing a Growing Plugin Ecosystem
Security, transparency, maintenance, and the systems behind a marketplace people can rely on.
 Li
- Research
How to Reduce AI Costs Without Losing Control of Your Stack
AI cost optimization requires visibility, governance, and reusable workflows to reduce spend without losing control.
Anne Zhu - Research
Build AI Applications, Not Platform Underneath: A Guide for IT Leaders
Here's how to build internal AI applications that reach production and survive the real world, without building the platform underneath them from scratch.
 Dify